TEL:+86 132 6656 7067


AI training and inference clusters depend on fast communication between GPUs, servers, and storage systems. As clusters scale, network performance becomes a critical factor in keeping accelerators productive. Insufficient bandwidth, congestion, inefficient topology, and limited optical connectivity can increase job completion time even when individual GPUs have substantial computing capacity.
Addressing these bottlenecks requires a coordinated design across GPU interconnects, network interface cards (NICs), switches, optical transceivers, and fiber infrastructure. The goal is to maintain predictable communication performance as traffic and cluster size increase.
1. Where AI Cluster Network Bottlenecks Occur
AI clusters exchange large volumes of data during distributed training, model synchronization, checkpointing, and inference. Bottlenecks can develop at several points along the communication path.
GPU interconnects: Limited NVLink or PCIe bandwidth can restrict communication between GPUs within a server.
Server-to-network interfaces: NIC capacity, PCIe connectivity, and GPU-to-NIC data paths can limit throughput.
Network fabric: Oversubscribed uplinks, congested switch ports, and uneven traffic distribution can reduce effective bandwidth.
Optical links: Insufficient link capacity, incompatible transceivers, or inadequate fiber infrastructure can restrict connectivity between switches and racks.
Storage and data delivery: Slow dataset loading or checkpoint transfers can leave GPUs waiting even when the compute network is functioning correctly.
A GPU cluster should therefore be evaluated as an end-to-end system. Upgrading switch bandwidth alone will not resolve a bottleneck caused by PCIe contention, inefficient GPU placement, or a storage subsystem that cannot feed data quickly enough.
2. GPU Communication and Network Traffic
Distributed AI workloads rely on frequent communication between GPUs. Operations such as AllReduce, AllGather, and ReduceScatter synchronize model parameters, gradients, or intermediate data across multiple devices and servers.
Within a server, communication performance depends on GPU interconnect topology and access to shared resources. Across servers, data moves through NICs and the network fabric. If one part of the communication path is slower than the others, it can limit the performance of the complete workload.
Collective operations can also generate synchronized traffic bursts. Many endpoints may transmit toward a shared destination at nearly the same time, temporarily exceeding the available capacity of a link or switch path.
Workload performance therefore depends on more than peak link speed. Communication algorithms, topology awareness, GPU placement, traffic distribution, and overlap between computation and data transfer all influence the effective throughput of a cluster.
3. Network Topology, Oversubscription, and Bandwidth
The network topology determines how traffic travels between GPU servers and how much bandwidth is available when many servers communicate simultaneously. Leaf-spine fabrics are widely used because they provide scalable connectivity and predictable paths between racks when designed with sufficient capacity.
Oversubscription occurs when the aggregate bandwidth offered by downstream ports exceeds the bandwidth available on their shared uplinks. This may reduce infrastructure cost, but it can create contention during communication-intensive AI workloads.
| Network Issue | Performance Impact | Design Consideration |
|---|---|---|
| Oversubscribed uplinks | Multiple servers compete for limited upstream capacity | Size uplinks for expected collective traffic and peak demand |
| Uneven traffic distribution | Some links become congested while others remain underused | Review load balancing, routing, and flow distribution |
| Excessive network hops | Additional forwarding and queueing can increase latency | Optimize topology and placement of communicating servers |
| Insufficient NIC capacity | Network throughput falls below the demand generated by GPUs | Match NIC bandwidth and host connectivity to workload requirements |
| Shared infrastructure contention | AI traffic competes with storage or other applications | Use capacity planning and appropriate traffic isolation or prioritization |
Increasing network capacity is one option, but the full topology must be considered. Balanced link utilization, sufficient switch capacity, appropriate routing, and suitable placement of workload components can improve performance without indiscriminately upgrading every connection.
4. Congestion, Packet Loss, and Latency
Congestion occurs when traffic arrives at a network resource faster than it can be forwarded. Queue buildup increases latency, while packet loss and retransmissions can reduce effective throughput. In distributed training, communication delays may cause some GPUs to wait for slower participants before the next computation stage can proceed.
InfiniBand and Ethernet-based RoCEv2 are both used for AI cluster networking. RoCEv2 can use technologies such as Explicit Congestion Notification (ECN) and, in appropriate lossless configurations, Priority Flow Control (PFC). Their configuration must match the selected network design; enabling isolated flow-control settings without understanding the full traffic behavior can create additional problems.
Congestion management should be paired with traffic engineering and end-to-end monitoring. Network teams need visibility into link utilization, queue behavior, packet drops, latency, retransmissions, and NIC performance to determine whether congestion is the actual cause of poor workload efficiency.
5. Optical Interconnects and Fiber Capacity
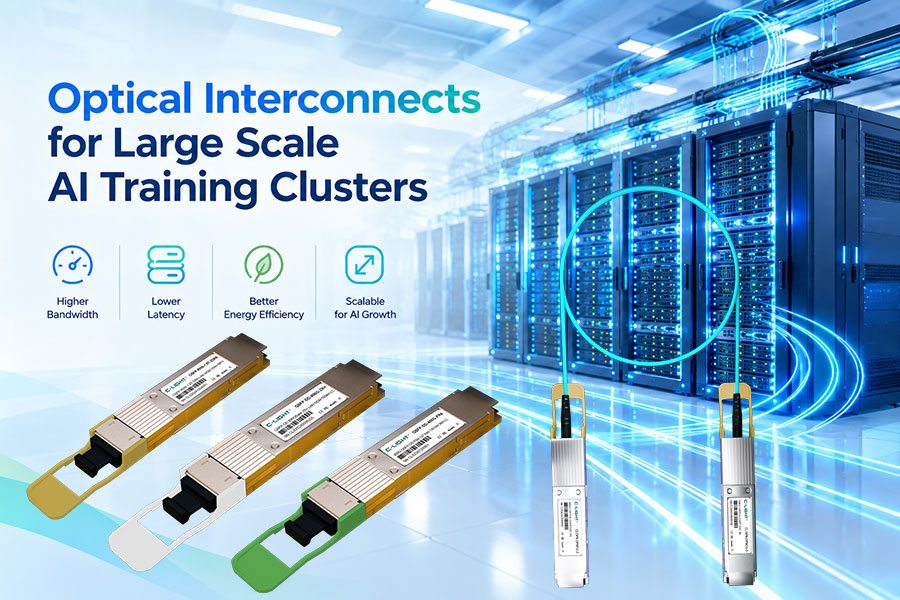
Optical transceivers and fiber links connect high-speed switches across racks, rows, and data center facilities. As aggregate AI traffic grows, 100G, 400G, and 800G links provide different options for scaling network capacity, depending on the switch platform and optical interface.
Higher-speed optics can increase bandwidth per port and reduce the number of individual links needed for a given aggregate capacity. However, the result depends on supported port speeds, switch architecture, module power, thermal limits, optical reach, and the number of available switch ports.
Fiber availability can become a separate constraint in large deployments. Wavelength-division multiplexing (WDM) can carry multiple optical channels over suitable fiber infrastructure, helping increase capacity where fiber strands are limited and the optical system supports the required design.
Transceiver selection should match the data rate, Ethernet standard, fiber type, wavelength, connector, reach, and link budget. Link stability also depends on connector cleanliness, correct fiber polarity, and adequate received optical power.
6. How to Identify and Reduce Bottlenecks
Effective troubleshooting starts by measuring each part of the communication path before making hardware changes.
Measure GPU communication: Compare expected and observed intra-node and inter-node bandwidth using suitable GPU and network benchmarks.
Inspect host connectivity: Verify GPU-to-NIC topology, PCIe bandwidth, NIC configuration, driver versions, and direct GPU memory access where supported.
Monitor the fabric: Track port utilization, congestion, packet drops, queue behavior, error counters, and end-to-end latency.
Check optical links: Review transceiver diagnostics, received optical power, link errors, and compatibility with the host platform.
Validate the workload: Determine whether low performance comes from networking, data loading, application settings, or inefficient communication patterns.
Test under realistic traffic: Validate the design at representative cluster scale rather than relying only on single-link throughput.
Network and application measurements should be considered together. If link bandwidth and latency meet expectations but AI communication remains slow, the investigation may need to focus on collective algorithms, GPU placement, CPU and memory affinity, or workload synchronization.
7. Building a Scalable AI Network
A scalable AI network balances computing capacity, intra-node connectivity, server-facing NIC bandwidth, switch capacity, and optical transport. Each layer must support the expected communication pattern without creating a persistent bottleneck at the next layer.
For large GPU clusters, network planning should include:
Bandwidth and port-count calculations based on the number of GPUs and servers.
A topology that provides appropriate paths and capacity for collective traffic.
Congestion management and monitoring suited to InfiniBand or the selected Ethernet architecture.
Optical modules and fiber infrastructure matched to link speed, reach, power, and thermal requirements.
Capacity headroom for workload growth, failure scenarios, and future accelerator upgrades.
Scalability is not determined by any single component. A balanced design allows GPUs, servers, switches, and optical links to operate together without one layer consistently limiting the others.
8. Conclusion
AI cluster network bottlenecks can originate in GPU interconnects, NICs, switch fabrics, congestion control, optical links, or data delivery systems. Their impact is most visible when distributed workloads require frequent, high-volume communication between GPUs.
Improving performance starts with identifying the limiting resource. Balanced topology, sufficient bandwidth, effective congestion management, compatible high-speed optics, and end-to-end monitoring help maintain predictable throughput as clusters expand.
 >

 >
 >
 >
 >
 >
 >
 >